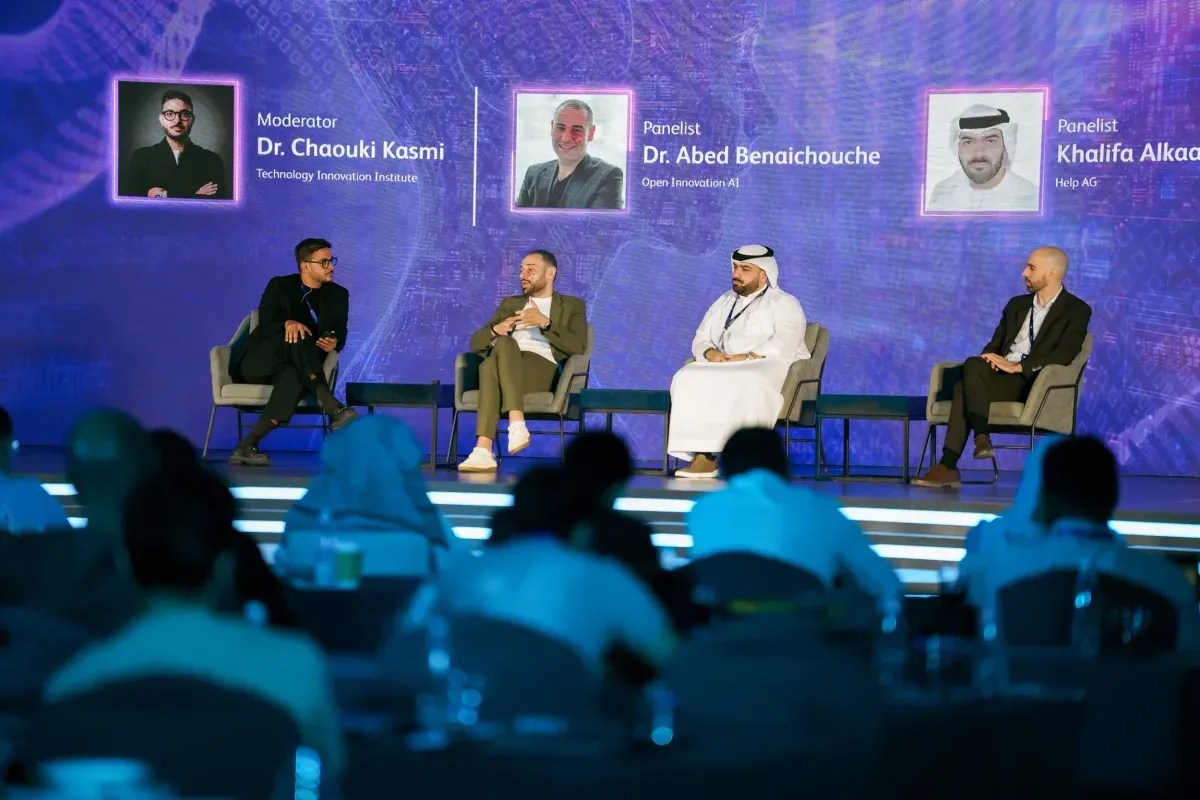
The UAE AI Expo demo had two halves, and the second half only works because of the first. Half one: a marked CIPD script, run through Sokros 3.0 live on stage, twice, in front of the room. Same grade, same quotes, same record, both times. Half two: the same system handed an unfamiliar brief it had never seen, reasoning its way to the evidence that mattered while the audience watched it think.
Most vendors demo one or the other. The reasoning system improvises brilliantly and cannot be trusted with a certificate; the deterministic system is trustworthy and rigid as a fence post. The whole argument of 3.0 is that a serious assessment system has to be both, and that the only way to be both is to draw the line between them in writing and refuse to move it.
The line 3.0 draws
Here is the line, exactly as we drew it on stage. On one side: everything where roaming helps. Finding the passage in a forty-page submission that speaks to a criterion. Proposing which assessment criterion a paragraph is arguing for. Drafting feedback wording for an assessor to edit. Searching, proposing, drafting: work where a clever wrong turn gets caught downstream and costs nothing.
On the other side: everything a learner's future rests on. Whether a criterion is met. Which band a script sits in. The record of the decision, and its replay. On that side the system does not reason at all. It checks written rules against quoted evidence and stores the answer. Nothing predictive sits between the evidence and the outcome.
Sokros 3.0 · the reasoning boundary
Free to reason
- Searching a submission for the passage that speaks to a criterion
- Proposing which assessment criterion a paragraph argues for
- Drafting feedback wording for an assessor to edit and send
- Summarising a moderation sample before a person reads it
Must not move
- Whether a criterion is met: a written rule, quoted evidence, present or not
- The band a script sits in, judged against your descriptors
- The decision record: verdict, rule, quote, model version
- The replay: same script in, same grade out, every run
Why the line is the product
Ask a generative model the same question twice and you get two answers. That is not a flaw to be patched; it is what the technology is. An institution cannot certify a coin flip, and no prompt template changes that. So 3.0 does not ask probability to behave like policy. It gives probability the work it is genuinely good at, and keeps it away from the work only rules may do.
There is a second failure mode the line closes, and it is the quieter one. Generative markers can be charmed: fluent prose earns marks that plain English is refused, and the bias sits in the phrasing rather than the evidence. A written rule checking quoted evidence does not read fluency. It reads for the thing the criterion asked for. The learner who writes plainly and answers fully stops paying the eloquence tax.
What 3.0 already carries
A line on a slide is a claim. What 3.0 carries in production is the proof. Every release since the 3.0 line was drawn has shipped through the replay gate: the calibration set, dozens of human-marked scripts, not thousands, plus every past case on record, compared byte for byte. If a single calibration script flips between Refer and a clear Pass, the release is blocked. Not flagged. Blocked.
The discipline compounds. Each release adds its decisions to the replay corpus, so the gate gets stricter as the footprint grows. That is why ministries and awarding bodies running frontier deployments treat 3.0 as infrastructure rather than software: the system they audit next March behaves exactly like the system they approved last March, and they can prove it without calling us.
Sokros 3.0 · production record to date
Releases shipped through the replay gate since 3.0 entered production
14
every one byte-clean
Calibration scripts flipped between Refer and a clear Pass, across all releases
0
Recorded judgements available for byte-identical replay
1.9m
+410k this quarter
Centres and markets marking on the 3.0 line today
34 · 20
Every release, every time
- 01 · Calibration setdozens of human-marked scripts
- 02 · Replay suiteevery past case re-run
- 03 · Byte compareany drift stops the release
- 04 · Shipsame grade, whoever asks
Reasoning finds the evidence. Rules decide what it means. The record proves it happened.
What changes for centres already live
For the centres marking on Sokros today, almost nothing moves, and that is the point. Their criteria stay theirs. Their calibration sets stay intact. What 3.0 adds is reach on the reasoning side of the line: better evidence-finding on long submissions, cleaner feedback drafts, sharper summaries for moderation. The judging side carries the same written rules it always has, replayed and byte-compared before anything ships.
Problem solving where it helps. Determinism where it counts. The line between them is not a limitation of the system. It is the system.